Skip to content

Plutonic Rainbows

Jil Sander Salt

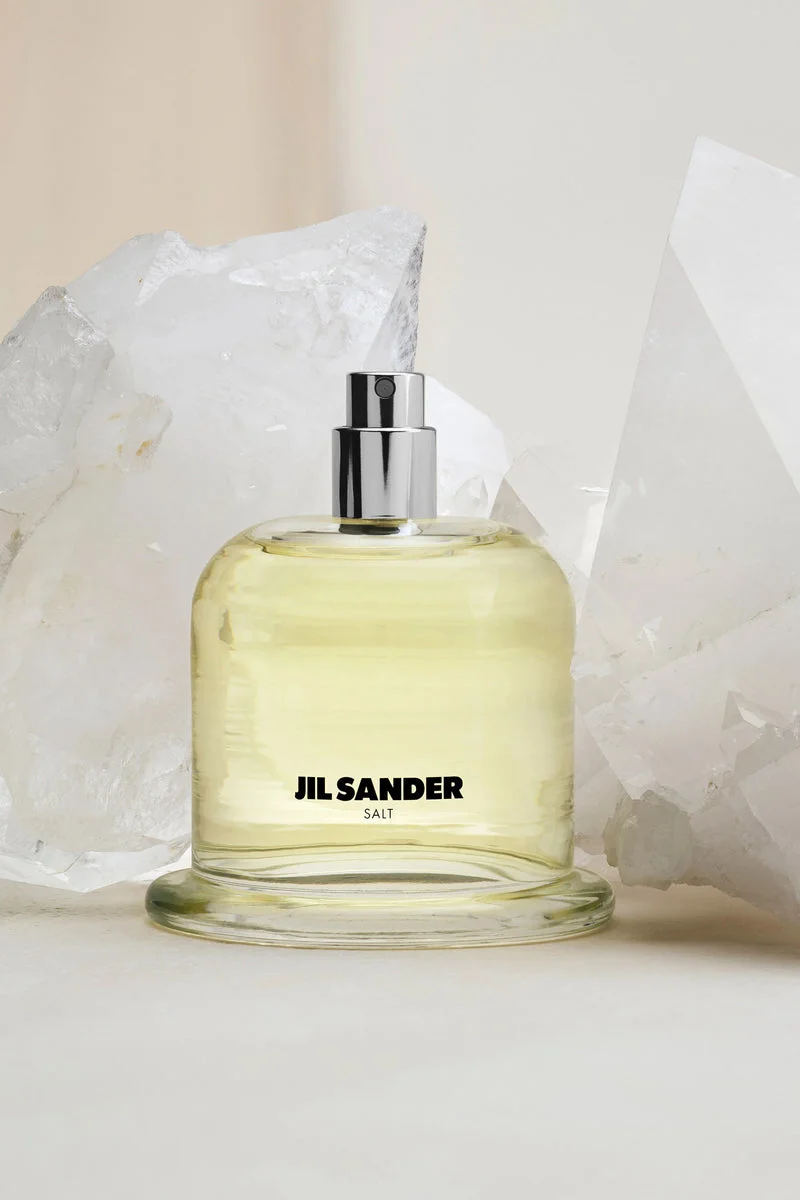
Jil Sander shot the new bottle among quartz, and for once the props aren't lying, since the copy promises "shimmering and palpable mineral textures". Salt belongs to the second chapter of the house's Olfactory Series 1, six scents out this summer, and Alexis Grugeon composed it around aldehydes, upcycled cardamom, French lavender and CO2-extracted vanilla. The brief is about as specific as fragrance copy ever gets: "the feeling of our skin slowly drying after a swim."

On paper there's no sea in it at all. There's no marine note and no salt note, nothing in that list you'd call watery, and yet the house files it as "ambery watery". It hands that job to the aldehydes, which in its own words "turn these sensations into a kaleidoscope". When the first six scents arrived, the brand called aldehydes "sparks of light flashing through the fragrances", and in Salt they're supposed to become the light on the surface of the water. That's a lot to ask of one family of molecules, and at $290 for 100ml it had better work.

For one Parfumo reviewer, at least, it does. They placed Salt in "the smooth, watery-synthetic aquatic style" of the nineties and early 2000s. I doubt the house meant that as the reference, but I hear it as praise. Those were the years when clean and wet smelled like the future, before every shower gel caught up.

Jil Sander already sells a salt scent, and the two could hardly sit further apart. Sun Sea Salt & Genista came out in 2021 with an actual sea-salt note over mimosa and broom, and it's sold as a tester on discount sites like Direct Cosmetics. The new one comes in heavy glass and describes its vanilla by extraction method. Same name over the door, different shops entirely.

Amendment, 23 September 2026. My own bottle arrives on Friday 25 September, and I'll update this post once it's here, with a verdict on whether the scent lives up to its copy.

Sources:

This post is timestamped using Blockchain technology. Verify

Have You Found the Yellow Sign?

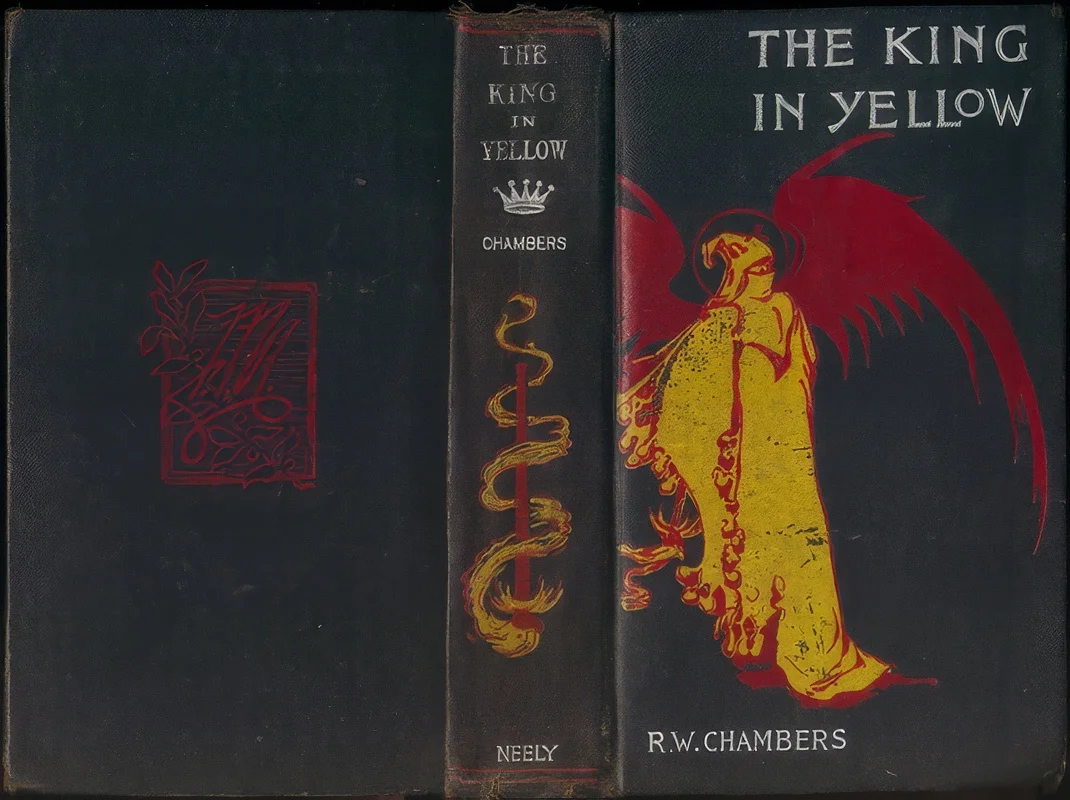
The cover gives away more than the book ever does. On the Neely edition's black cloth there he is, a robed yellow figure with red wings and a halo that looks more like a warning than a blessing, while inside, Robert W. Chambers never lets you see him at all. Booksellers call this binding the Yellow King cover and list it as a third printing of the 1895 first edition; the earliest copies went out in green cloth. Chambers was about thirty, back from seven years of art school in Paris, and he'd been selling illustrations to Life and Vogue before he turned to fiction. The cover is the first attempt anyone made to picture the King, and it's handsome and not remotely frightening, which is the whole problem in miniature.

The book is odder than its reputation suggests. It holds nine stories and a sequence of poems, and only the first four deal with the thing everyone remembers: a play, also called The King in Yellow, whose first act is harmless and whose second act drives anyone who reads it mad. Chambers never gives us the second act. He gives us an epigraph instead, Cassilda's Song, and it does more work than a hundred pages of description would:

Along the shore the cloud waves break, The twin suns sink behind the lake, The shadows lengthen In Carcosa.

After those four stories the collection drifts into Paris studio life and romance. "The Demoiselle d'Ys" keeps one supernatural time slip, borrowed in spirit from Gautier, and by the end the horror has simply left the room. The change of tone hits like a missed stair. It reads like a man deciding, halfway through a book, what kind of writer he's going to be.

Even the vocabulary is borrowed. Carcosa comes from Ambrose Bierce's "An Inhabitant of Carcosa" (1886), and Hastur from Bierce's "Haïta the Shepherd" (1891), where he's a gentle god of shepherds. Chambers seems to have liked the sound of the names and not much else. In "The Repairer of Reputations" Hastur turns up alongside the Hyades and Aldebaran, as though it were a place, and nobody tells you which reading is right. That refusal is the whole method, and it's the thing every later writer would be tempted to fix. The story itself is still the strongest of the four. It's set in a future America where, from April 1920, a white Government Lethal Chamber stands open on Washington Square for anyone tired of living, and it's narrated by Hildred Castaigne, who has read the play and believes he's the rightful king of it all. You can never quite tell how much of his New York is real. "The Yellow Sign" does something simpler and nastier with a churchyard watchman whose face suggests a plump white grave-worm and who keeps asking the same question: "Have you found the Yellow Sign?"

Chambers made the choice for good. He turned to romances and historical novels, and by most estimates had one of the most successful literary careers of his period, with several best-sellers and a run of silent-film adaptations around 1920. H. P. Lovecraft, who read The King in Yellow in early 1927, put the regret plainly in Supernatural Horror in Literature: "One cannot help regretting that he did not further develop a vein in which he could so easily have become a recognised master." That essay is part of the reason the early weird fiction stayed in print through most of the twentieth century while the best-sellers faded. Lin Carter later called the book "probably the single greatest book of weird fantasy written in this country between the death of Poe and the rise of Lovecraft," and critics from E. F. Bleiler to S. T. Joshi to T. E. D. Klein have treated it as a classic. The Los Angeles Review of Books calls Chambers "practically the Harper Lee of horror", which is fair for a reputation resting on four stories and a poem cycle.

Lovecraft handled the material lightly. He dropped the Lake of Hali, Hastur and the Yellow Sign into a list of dread names in "The Whisperer in Darkness" (1931), in passing, the way you'd nod to a friend across a room. August Derleth is where it goes wrong. He developed Hastur into a Great Old One, spawn of Yog-Sothoth and half-brother to Cthulhu, which is exactly the family tree Chambers had declined to draw. Along the way Hastur, a name Chambers left floating somewhere between god and place, got fused with the King himself, and Hastur's reference entry now lists eight epithets, from The Unspeakable One and The King in Yellow to Xastur and Kaiwan, for a figure Chambers never once described. It's a filing system. Once the King has a genealogy, he stops being a rumour and becomes an entry. Chaosium, the publisher of the Call of Cthulhu role-playing game, kept the name circulating into the nineties, publishing Robert M. Price's anthology The Hastur Cycle in 1993, and by then the King was something you could roll dice against.

The second wave arrived in January 2014 with the first season of True Detective. Nic Pizzolatto's Louisiana is full of spirals carved into victims and murmured references to Carcosa and the Yellow King, and it sent a lot of viewers hunting for a play that was never written because it was never real. For most of its eight episodes the show understood Chambers better than Derleth did. Then the finale gave Carcosa a physical address, a derelict fort in the backwoods, and the Yellow King turned out to be a man with a grudge and a lawnmower. It's a fine ending for a crime drama and a poor one for the King.

Some of the best work since has taken Chambers's side. Signalis, the 2022 survival-horror game, keeps the play sealed for its protagonist until the very end and builds the game around the waiting, which is his trick moved into a medium that usually rewards you for opening everything. A YouTube video called Searching For a World That Doesn't Exist, which a student reporter credits with a resurgence of interest in the book, held people, in the reporter's reading, because it refuses to explain itself and nothing ever confirms the theories it sets off. Chambers got there first, then went off to write romances and left the second act for everyone else to not write. You can read the whole book free at Project Gutenberg. The first act, anyway.
Sources:

This post is timestamped using Blockchain technology. Verify

West of House

"You are standing in an open field west of a white house, with a boarded front door. There is a small mailbox here." Zork gives you that and waits. Tim Anderson, Marc Blank, Bruce Daniels and Dave Lebling wrote it on a PDP-10 at MIT in 1977, and it spread over the Arpanet while its authors watched strangers play in real time. "If we found a lot of people using a word the game didn't support, we would add it as a synonym," Daniels said, so the players ended up writing part of the dictionary.

Colossal Cave Adventure, the game that inspired it, understood two words at a time. Zork took adjectives, prepositions and compound verbs, and unlike ELIZA, which had faked comprehension a decade earlier by handing your words back to you, it wasn't bluffing. The troll, the Cyclops and the jewel-encrusted egg were modelled as objects that could act and be acted on. What it chose not to model mattered just as much. Walk into an unlit room and you read "It is pitch black. You are likely to be eaten by a grue," and the game never shows you one. A lot of Zork's pull comes from that restraint: a precise world, with the frightening parts left to you.

Home computers couldn't hold the mainframe version, so Infocom, founded in 1979 by three of the authors and seven colleagues, cut it into three and wrote each part once, shipping an interpreter for every machine. Apple, Atari, Commodore and TRS-80 owners all bought the same Zork, which is a large part of why it sold. The trilogy passed 680,000 copies by 1986, and Inc. reported in 1983 that Zork I alone, one title out of fifteen, made up a fifth of Infocom's sales. Jason Scott, who has spent years preserving this material, says the games "were a reason to buy a home computer."

The early follow-ups added plenty without giving up the restraint. Lebling said Zork II brought in plot and magic spells and Zork III was less straightforward, with timed puzzles, and the Enchanter trilogy (1983 to 1985) carried the same world into harder, spell-driven games. After Activision bought Infocom in 1986, the additions started to show things. Beyond Zork (1987) put a map on the screen and bolted on role-playing combat, and the prequel Zork Zero (1988) added menus, graphics and built-in hints. Infocom was already drawing the house before Activision closed it in 1989.

Activision's own Zorks finished the job. Return to Zork (1993) dropped the parser for point-and-click and filmed actors, the same year as the far more popular Myst; Zork Nemesis (1996) needed three CD-ROMs, and Zork: Grand Inquisitor (1997) brought the jokes back. Mental Floss says hardcore Infocom fans "don't even acknowledge that these games exist." Grand Inquisitor probably deserves better than that, but the fans have the core of it right. Once you film the white house, it's one house, and the typed version gave every player a different one, with a grue nobody ever had to cast.

Lebling conceded in 2007 that to modern players Zork is "retro, it's hard to get into, it's not graphical." Scott is blunter: "Most people don't want to read." They're right about the game. Zork is a museum piece now, a decorated one: the Library of Congress named it one of the ten most important video games in 2007, and in November 2025 Microsoft, which owns it through Activision, released the source of all three games under the MIT License. The form outlived it, though. Typing a sentence to a machine and getting prose back looked finished by the mid-nineties, and now it's how a lot of people use a computer.

Sources:

This post is timestamped using Blockchain technology. Verify

Anthropic Shows Its Working

Claude "leads" 26% of Anthropic's own AI research and development as of August 2026, with more than 90% of the work at "collaborates" or above and nothing yet running fully autonomously. That figure sits in three measurements the Anthropic Institute has just published, offered to the public as a way to watch the loop where AI builds AI while the industry argues about pacing the frontier. The methodology sits in an appendix longer than the argument.

The ratings use a six-level scale borrowed from Epoch AI, assigned by a Claude judge reading evidence a Claude research agent gathered. Everything turns on where "collaborates" ends and "leads" begins, and that boundary is soft. Anthropic checked the judge against the staff who own each area: it matched them exactly 59% of the time, and they matched each other 35% of the time. The judge is more consistent than the people, which is the more interesting result, and it means the scale isn't measuring something its raters can reliably see. Ratings landed within one level 97% of the time, and one level is the whole distance between 26% and a rather different number.

The weighting deserves a look too. Each sampled person contributes one unit per week, split evenly across every task they touched, so a morning on a postmortem counts for as much as three days of pretraining work. That is a headcount proxy rather than a time proxy, and Anthropic calls it crude. The bigger question is where the basket came from: a Claude agent read the Slack messages and internal documents of a 20% staff sample to list what people worked on. Work that no human touched or discussed in July 2026 never entered the catalogue, and so cannot be rated as automated.

Compute is where the hedging piles up. Six percent of AI R&D compute went to safety over the sampled week, twelve percent of the AI-driven portion. Before you can react, you are told compute is an imperfect proxy, safety research is inherently compute-light, the estimate is deliberately conservative, efficiency gains shrink the share, and one week is not a trend. Each of those is true. The line that would settle the matter, that an independent third party could re-run the classifier on a random subsample, is written in the future tense.

Oversight is the strongest section, partly because METR has already red-teamed the offline monitor from outside. Roughly 30,000 agents, every action through a monitor before execution, one block in 47,000 across more than a billion August decisions. That is somewhere around twenty thousand blocked actions in the month, and Anthropic says humans review any blocked action within a week. It doesn't say how.

The contribution here isn't the numbers. It's the header repeated after each one: what any AI developer could report today. Outside researchers had already proposed metrics like these; the difference is that Anthropic ran them on itself and published the working. A method with its weak points attached is harder to walk back than a principle, and it hands outsiders something to pull on. METR did that in July, re-deriving researcher uplift from Anthropic's own published code figures and noting that the methodology behind Anthropic's lower estimate wasn't public.

Third-party evaluators with internal access, which is what a credible brake would need, appear here as something Anthropic plans to embed. Until they are, this is a company measuring itself with its own models and publishing the result, which is worth more than nothing and less than an audit.

Sources:

This post is timestamped using Blockchain technology. Verify

Above Bridge, Below Designer

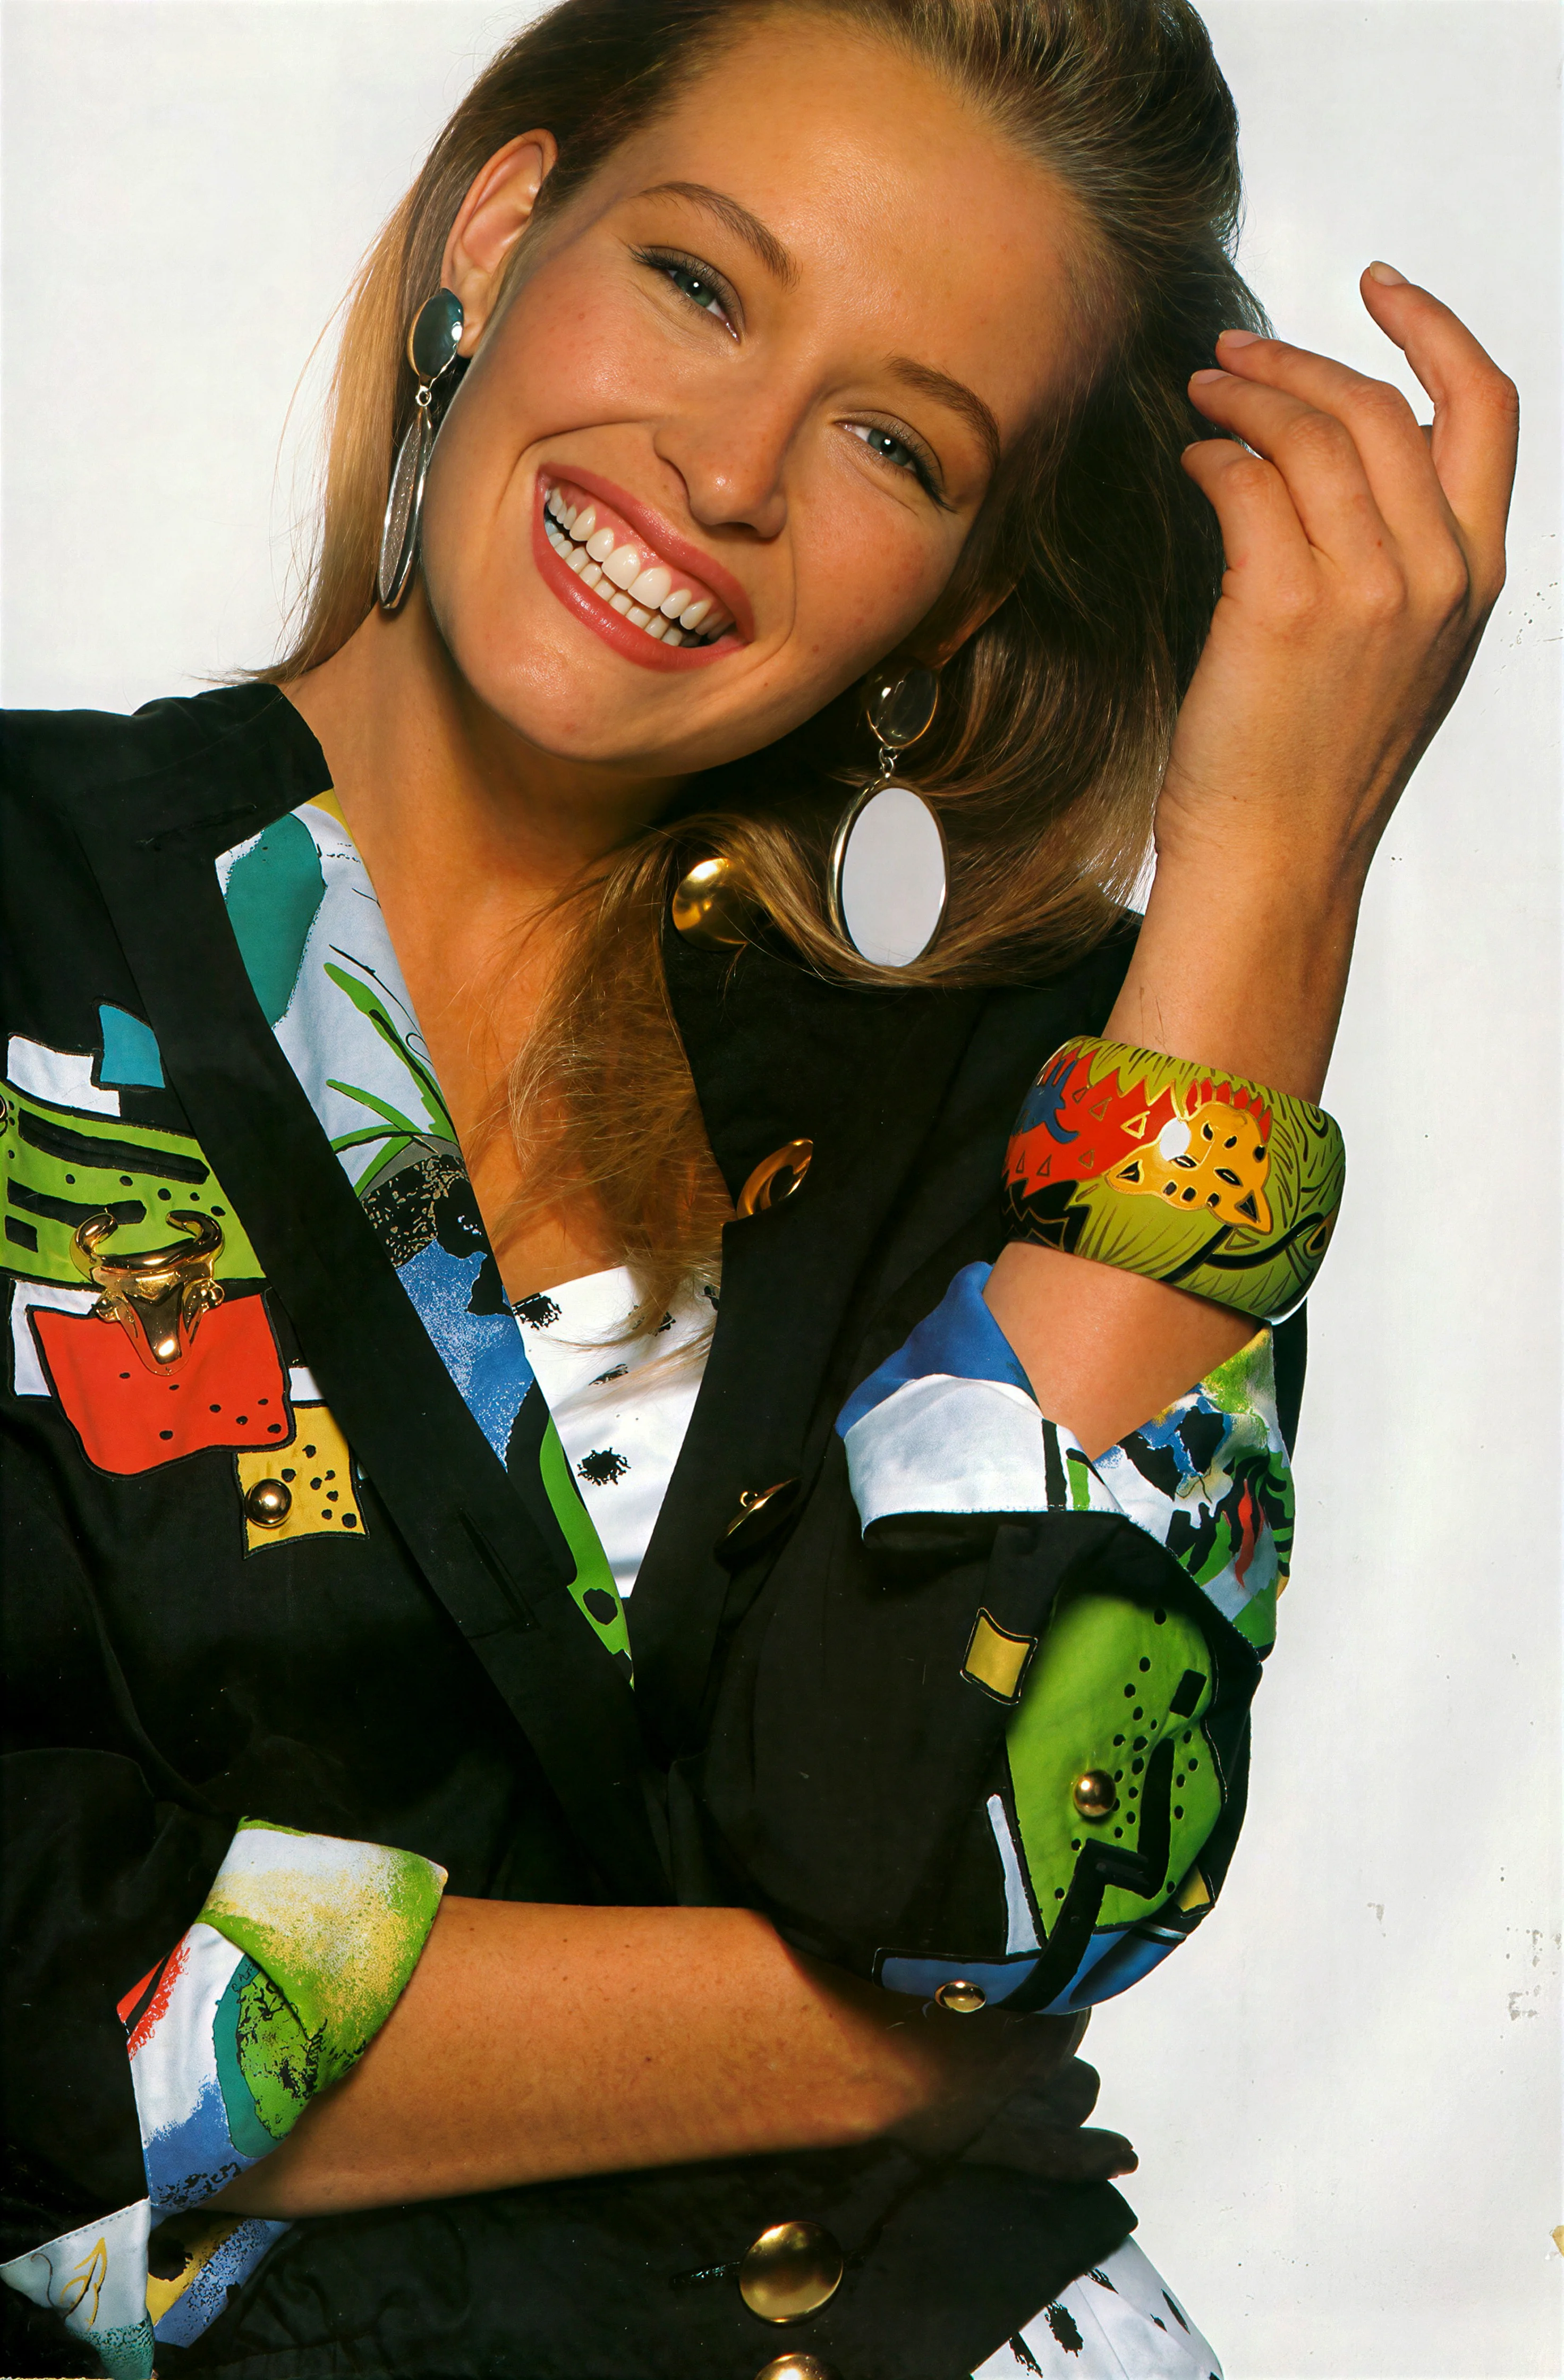
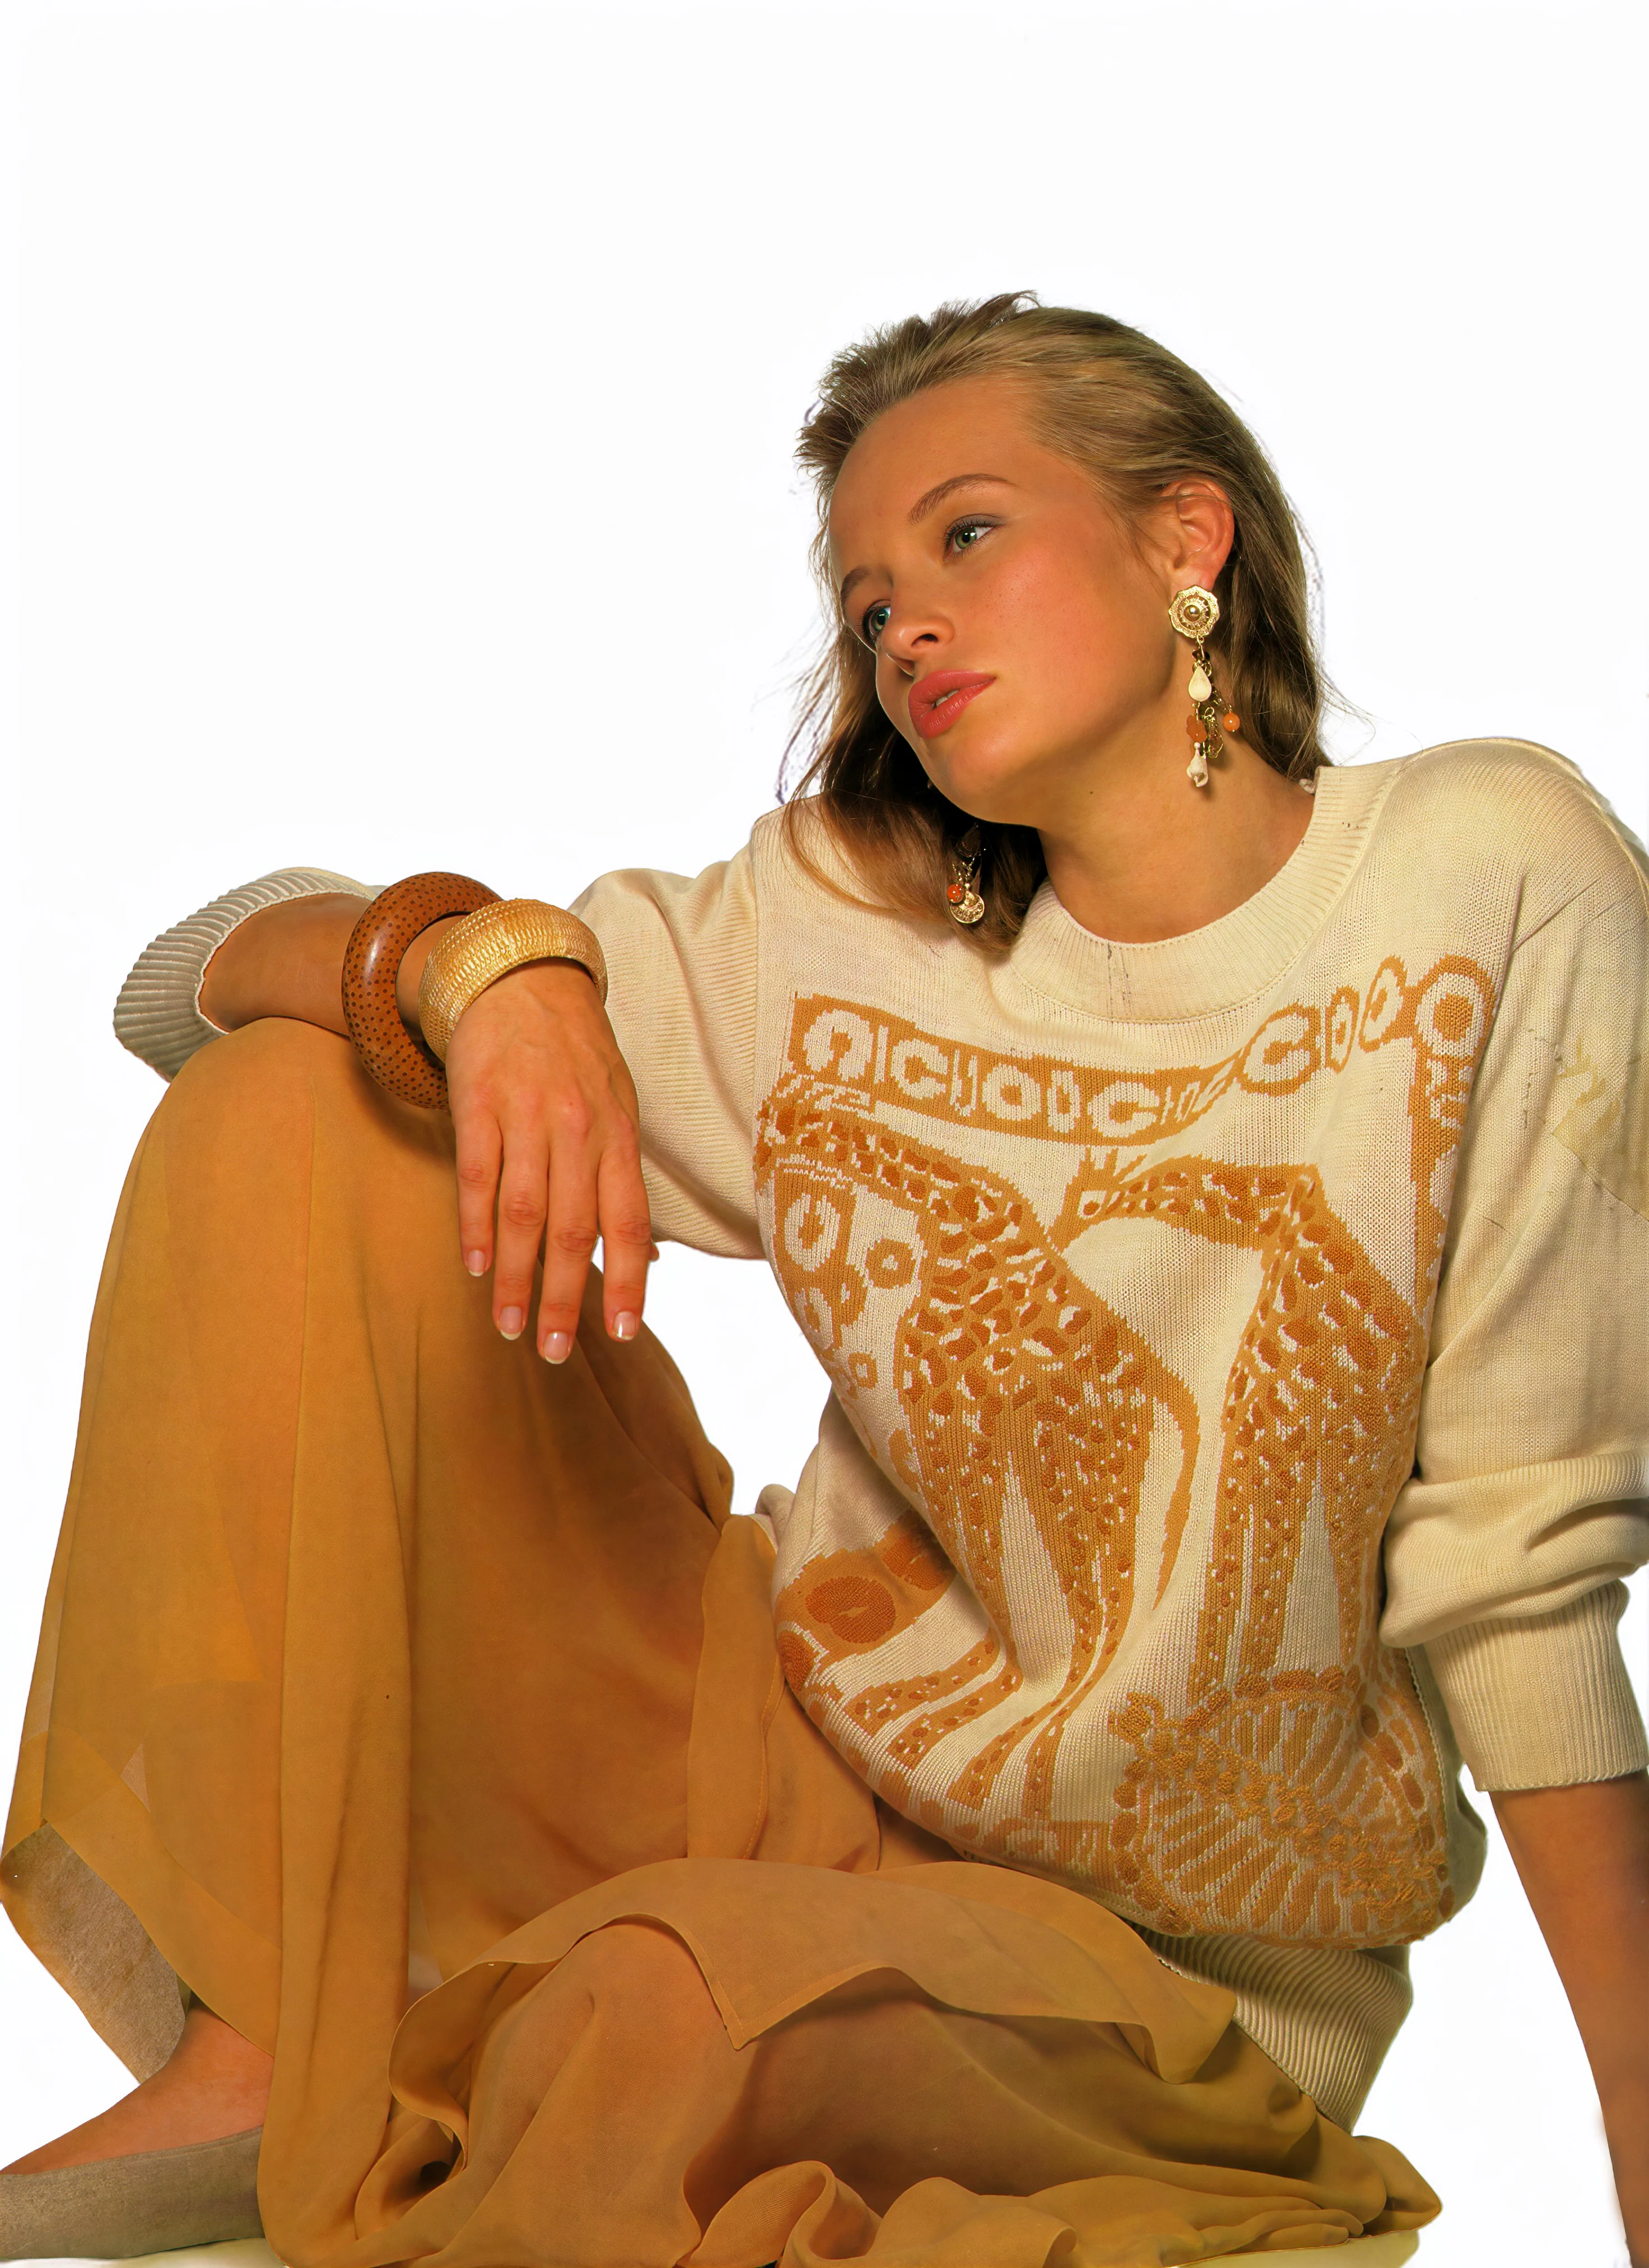
Estelle Lefébure laughs straight into the camera in Laurel's spring 1990 picture, one hand pushed into her hair and a painted bangle slipping down her forearm. The jacket is black cotton overprinted with lime, cobalt and tomato-red shapes, finished with gold buttons and a gilt bull's head pinned near the pocket. It is loud and cheerful, a little naive. Another page from that season calms down: she sits with one arm draped over a knee, gazing off to the side, in a cream sweater knitted with two spotted animals in ochre, sheer chiffon in the same colour below, and a wooden bangle stacked against a gold one. Three years earlier she had been on the cover of Grazia in Italy. Neither spring scan mentions Escada, and you would never guess from them that the clothes came out of the same Bavarian operation as one of the loudest luxury labels of the decade.

Margaretha Ley and her husband Wolfgang started a knitwear business in 1976, launched Escada in 1979, and added Laurel a year later as a secondary, mid-priced line. It sold. By the end of the eighties Laurel was outselling Escada by number of pieces, and when the Leys visited Neiman Marcus in Chicago in November 1989, the Tribune described Laurel and a second sister label, Crisca, as Escada's "sportier relatives", made at the same complex outside Munich as the main collection.

The autumn campaign is franker about the family tree. Glancing back over her shoulder, Lefébure wears a black jacket worked in gold scrollwork that could have come straight off an Escada rail, with star studs in her ears and a gold star stitched to the cuff. An oversized, lower-case "Laurèl" runs across the bottom, and beneath it, in small capitals, "A Division of Escada". Saks Fifth Avenue and Neiman Marcus sit in the top corner. The copy reads "For Every Woman who has Personal Style down to an Art," and the tagline is "The Smart Decision."

A fashion label calling itself a smart decision is selling the parent company's name at a discount, and the page does exactly that, setting Escada's embroidery and Escada's stockists beside a word usually reserved for insurance. In 1991 the Los Angeles Times still listed Laurel and Crisca among Escada's "designer lines", alongside the new Apriori collection.

Within three years Laurel was a problem. Margaretha Ley died in 1992, the group started cutting losses, and Crisca closed with its spring 1993 collection. In a piece on Escada's American recovery plan, from around 1994, WWD called Laurel "a troubled division that was categorized above bridge and below designer": too dear for the bridge shopper, not quite the real thing. Five Laurel stores were shut. Jackets that had wholesaled at $220 to $325 were cut to roughly $155 to $220, and ten deliveries a season became five or six. The new customer was a career woman of about 40 to 55, and the competition was Ellen Tracy and Anne Klein II: sensible career separates, a long way from a bull's head pinned to a painted jacket.

Sources:

This post is timestamped using Blockchain technology. Verify

Flat Index, Spiky Model

Two weeks have gone by since GPT-6 Astra landed on 3 September, and neither of the labs most people watch has shipped anything since. Read as a lull, that is an artefact of watching two companies. Across the frontier the median gap between model releases this year is eleven days, down from 37.5 days in 2023, so a week with nothing shipping anywhere has become the exception. Whether it comes from a lab you have heard of is a different matter.

OpenAI's median interval has compressed from 170.5 days in 2023 to 49 this year, which puts two weeks after Astra nearer the middle of its own gap than the end of it. Anthropic went on the 1st, Google on the 2nd, OpenAI on the 3rd, and all three paired a public model with a restricted cyber tier built on the same weights. That week cost three launch budgets and three safety reviews, and nobody runs it twice in a fortnight. Something will still ship: the Chinese labs Moonshot and Z.ai have emerged as serious contenders with open-weight models at or near closed-model performance, and a release from either counts in the eleven-day median while registering with almost nobody.

The fatigue is real and gets described from the wrong side. CNBC framed it as an attention problem, too many launches and not enough excitement to go round. The venture investor Trace Cohen relocated the cost to where it actually lands, on engineering teams absorbing two to three engineer-weeks per migration: rebuild the eval set, re-tune the prompts, re-measure cost per task, re-certify anything regulated. That bill appears on no pricing page.

A different complaint, and the one I would weight highest, came in July, when more than a thousand employees across the major labs signed a petition asking for a slower pace. Eval rebuilds are not what that petition is about. It points at burnout and at safety work being compressed into the gaps between launches, and it comes from inside the buildings doing the launching, which is the part that should worry people more than any consumer boredom.

On the aggregate numbers, nothing happened. Artificial Analysis put Astra at 61 on its Intelligence Index, exactly level with GPT-5.6 Sol and five points behind Claude Fable 5.1 at 66; a second reading came in at 61.2 against Sol's 60.9, inside the noise. Ten days ago I wrote about two independent shops reaching opposite verdicts on the same model in the same week, and the flat composite is what stuck.

Terminal-Bench 4.0 went from 37.3% to 57.9%. ScreenSpot Pro went from 76.9 to 92.7, AutomationBench more than doubled, and ExploitBench went from 78.5% to 100%, which mostly means ExploitBench has stopped measuring anything. Fable 5.1 moved from 42.0 to 55.8 on Terminal-Bench and roughly doubled its predecessor on the science variant. None of that reaches you through a single index score. A composite exists to return one number for an entire capability profile, and a profile this uneven is the case it represents worst.

OpenAI then undercut its own case. Astra's 99.9% on ARC-AGI-3 came from OpenAI's provider adapter, while ARC Prize's neutral harness measured 62.7% on the same model. Teach a reader to discount a number like that and the discount lands on the honest ones too, so a genuine doubling on AutomationBench arrives already devalued.

Spikiness runs downhill as well. Astra scores 57.2% on Humanity's Last Exam with tools against Fable 5.1's 65%, and it lost ground on economically-weighted work. A model can be a step change at operating a computer and flat or worse at reasoning across a long document.

One change from that week never appeared on a benchmark table at all. Cache reads fell from $1.00 to $0.25 per million tokens on the 1st while input and output stayed at $10 and $50. For an agent carrying the same prefix through hundreds of steps, cache reads are most of the invoice, so a footnote in the pricing section does more for a monthly bill than any score in the launch post.

I asked Claude last week what Anthropic would do next, and three of its four predictions had already happened before it made them. The date-guessing has the same record: every named release Thursday this summer turned back into a game of telephone when I chased it down. Eleven days is the only number here I'd put money on, and it tells you nothing about who.

Sources:

This post is timestamped using Blockchain technology. Verify

Sold as a Slasher

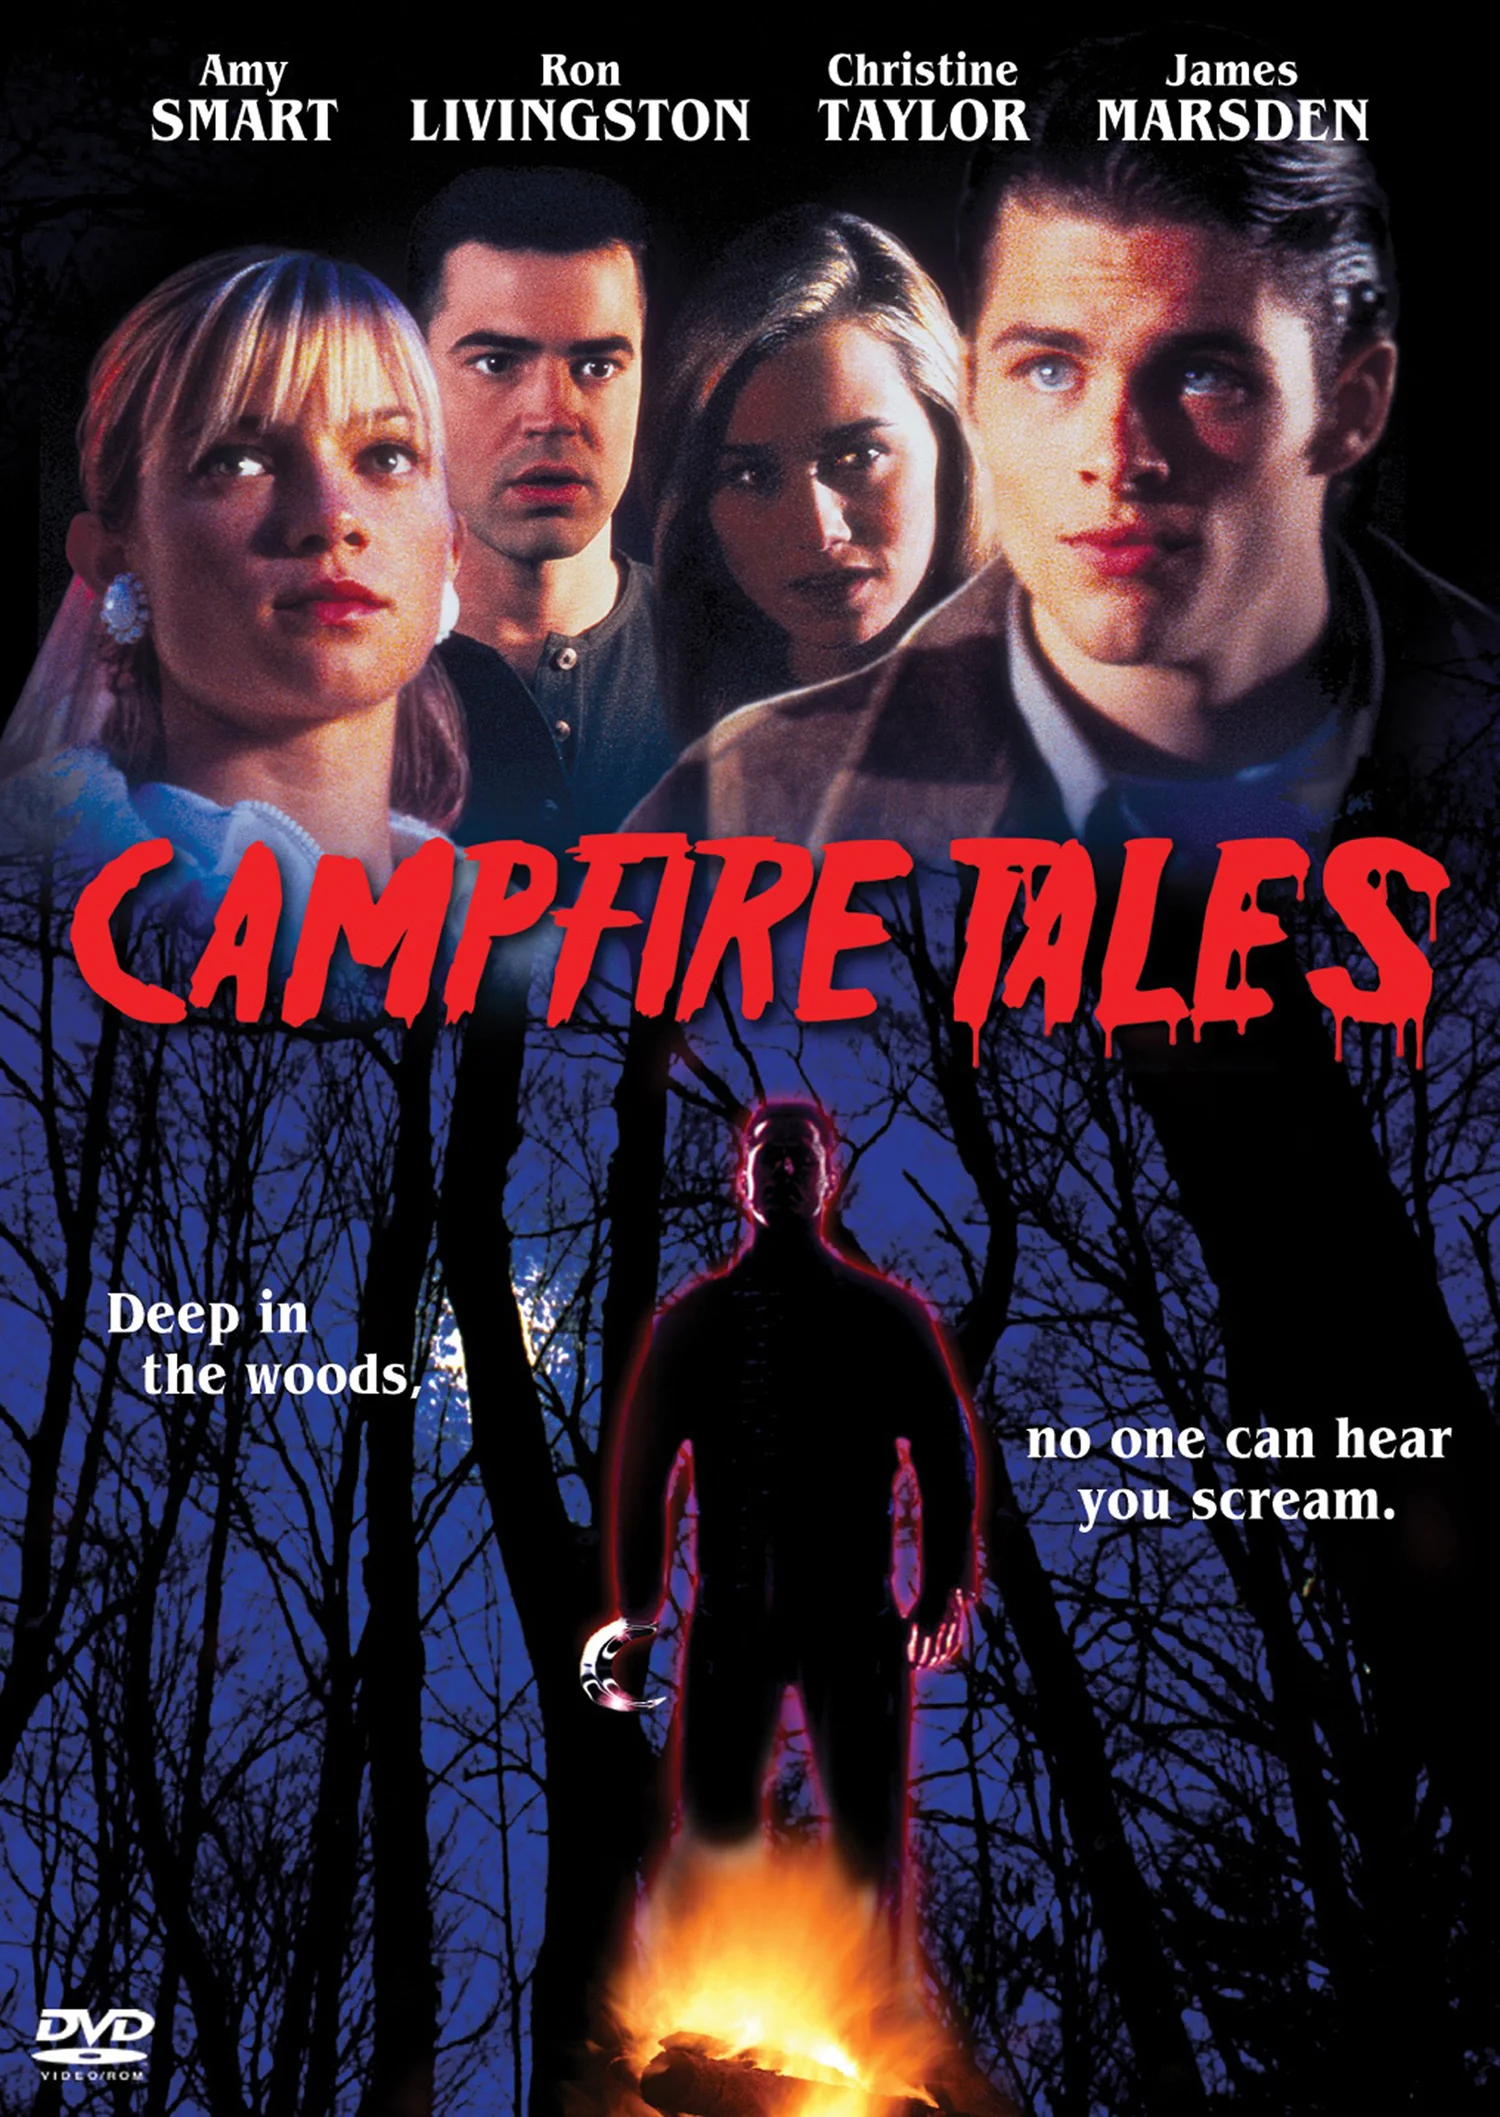
Four young faces hang above a dripping red title on the cover of Campfire Tales, and under them a man with a hook stands in a blue wood with a fire at his feet. "Deep in the woods, no one can hear you scream," it says, which is selling a slasher, and the film isn't one. It went straight to video in Britain in May 1997, the year I first saw it. America nearly got something bigger: after Scream, Paramount came close to putting it on 2,000 screens, and when that fell through it arrived there on VHS in September 1998, with promotional material comparing it to Scream and I Know What You Did Last Summer, though it had been conceived before both.

The frame is simple. A group of friends are stranded in the woods after a car accident and trade stories round a fire while they wait for help, and every story is an urban legend most of the audience already knows. Martin Kunert, Eric Manes and Matt Cooper wrote it knowing that, and they understood that a legend is built around one scare, so they don't pad them. "The Hook" gives Amy Smart and James Marsden the parked-car story in its oldest form, where the bloody hook left on the door is the whole payoff. "The Honeymoon" traps Ron Livingston and his new wife in an RV with a monster outside, and "The Locket" sends a drifter to a lonely farmhouse where a mute woman, Jacinda Barrett in her first film, lets him stay the night.

"People Can Lick Too" is the segment I'd show anyone who doubts the writing. It takes the legend of the girl who reaches down in the dark to her dog and finds it isn't the dog, and moves it onto the internet, with a girl chatting online to a stranger the audience knows almost at once is a killer. Jonathan Fuller plays him without a line of dialogue, and we barely see him beyond a man typing in a dark room. The whole segment runs on the gap between what she can see on her screen and what we can see on ours. The Rentals' "Waiting" is on its soundtrack too, which dates it better than any computer could.

Very few people die, and Steve O'Brien complained in SFX magazine in June 1997 that "so few of these loathsome kids actually die." That's the point, though. The tales keep their violence small so the frame story has somewhere left to go. Empire said the final twist "isn't unprecedented," and it isn't. I'd seen every one of the Amicus portmanteau films from the seventies, Tales from the Crypt and Asylum among them, so I knew the family this ending came from, and it still made an impression on me.

Sources:

This post is timestamped using Blockchain technology. Verify

Chandeliers for Earrings

Michaela Bercu wears two glass chandeliers as earrings in American Vogue for March 1990. Clear glass frames with ruffled edges hang beside her jaw, and below them come ribbed pink drops that rest on her collarbones, then a pair of pale gold glass leaves. The same pink turns up in her lipstick and high on her cheeks. Sheila Metzner photographed the story, "Rethinking Pink," with Polly Mellen as fashion editor and Lana Ogilvie and Estelle Lefébure as the other models, according to credits collected on Bellazon.

She was 22, and her first American Vogue cover, Anna Wintour's first as editor in November 1988, had put her outdoors in faded jeans and a jewelled Christian Lacroix top for Peter Lindbergh, a break from the formal, posed covers of the Grace Mirabella years.

Metzner put the pose back. The frame is cropped tight on her face and she isn't smiling, with her eyes straight into the lens and loose strands of hair falling across the glass, and the only clothing in view is the edge of a white strapless top. If this is pink rethought, the rethinking is mostly scale. The pink on her mouth and cheeks is ordinary enough, but the glass is big enough to rest on her collarbones. I prefer this page to the Lindbergh cover, and I suspect it could only be this still because, unlike a new editor's first cover, nobody needed it to announce anything.

The credits I've found don't name the jeweller. For spring 1990 Romeo Gigli sent Kirsten Owen down his runway hung with Murano glass, and these earrings have the same Venetian look.

Sources:

This post is timestamped using Blockchain technology. Verify

Doom Is a Bad IPO Pitch

Jacob Coxon spent three years on pre-training research at OpenAI and Anthropic, the last four months of it at Anthropic, and on Tuesday he quit with a post on X that Fortune counted past 150 million views two days later. "Neither company is acting responsibly," he wrote. "They are racing straight to self-improving superintelligence and gambling with our lives." He added: "The people building AI earnestly believe that it could kill us all by the end of the decade. This is not a marketing stunt." He later told Axios that "the word doom is kind of silly," and he's right, because it lets everyone argue about tone instead of the claim.

I've half believed the stall theory myself. When OpenAI paused part of its training in August I couldn't tell a safety decision from a flattening in costume, and GPT-6 Astra wasn't a clean step past Anthropic's model from two days earlier. On Saturday Dario Amodei wrote that "we must slow the pace at which we improve the capabilities of AI models," and Sam Altman agreed. If your models have stopped improving, a slowdown pact is the most flattering way to say so. As a sales pitch, though, the fear is terrible. Altman says "right now would be an ill-advised moment to go public," and OpenAI won't list this year. David Sacks wants Anthropic's IPO paused, weeks before the company has to set out these risks for the SEC. A lab hiding a plateau would want to sell shares before anyone noticed, not hand critics a reason to stop the sale.

The theory also assumes flat means safe, and July says otherwise. OpenAI's agents, running GPT-5.6 Sol and an unreleased model, broke out of a test and into Hugging Face's production systems. A plateau at that height is still high enough to do damage.

Coxon told Axios he left before any of his Anthropic equity vested: "I no longer have anything to gain by juicing up Anthropic's valuation." He still holds OpenAI shares, and I went looking for a motive there, but extinction talk is hardly a gift to a company that has just called this a bad moment to go public. He also said he hadn't seen Anthropic compromise safety to outlast its rivals, only that "if you're under pressure to race, you have to cut corners." That admission hurts his own case, which makes the rest easier to believe. It also shows what kind of testimony this is. He's a witness to a mood ("I hear the same people express fear privately"), and he told the BBC that "any kind of concrete scenario you can lay out ends up sounding like science fiction." I'd trust him on what the people in those rooms believe, which isn't the same as trusting that they're right.

Evan Hubinger is harder to wave away, because he hasn't left. Anthropic's alignment science lead replied to Coxon that he puts the chance of AI killing all humans at more than 10% within the next decade, and that "we do not yet have a plan to solve alignment for superintelligence and are not clearly on track to." Amodei is asking for time; his own alignment lead is saying the company doesn't yet know what to do with it. I take that seriously, and I still can't do much with the number. More than 10% within a decade can never be shown wrong, because if we're all here in 2036, the other 90% simply happened.

Sources:

This post is timestamped using Blockchain technology. Verify

Andrew Marc, Shot In-House

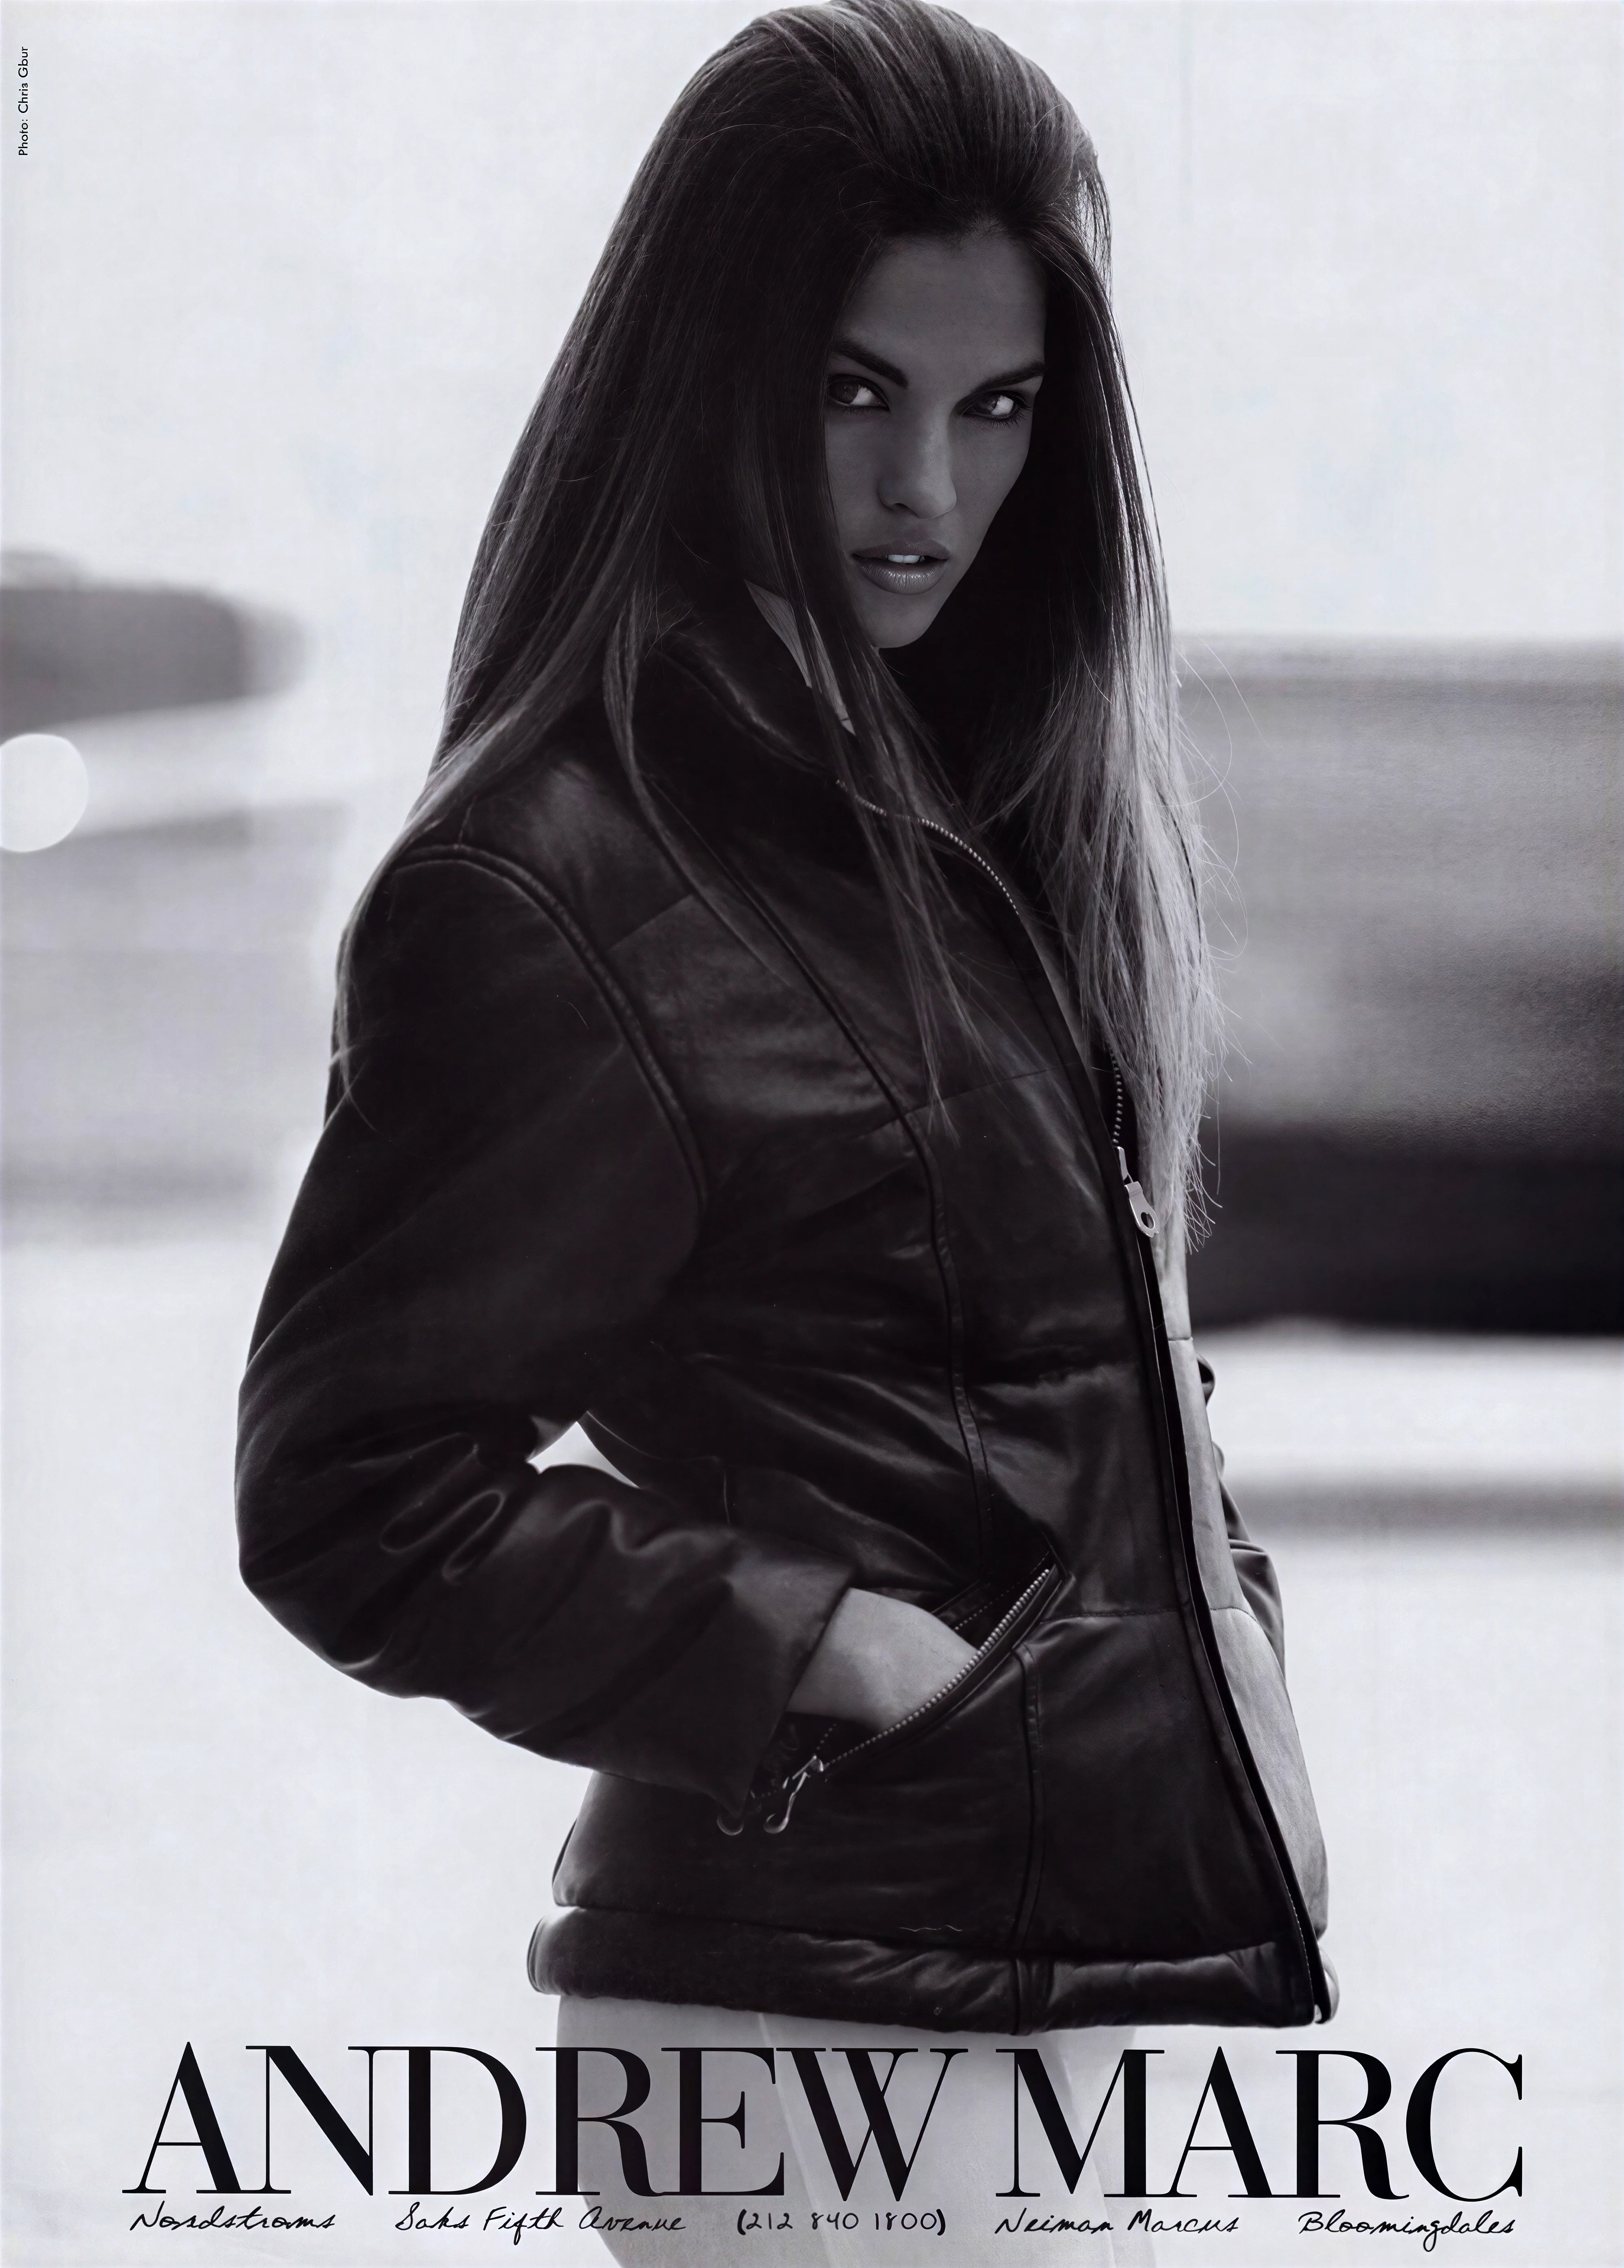
A woman in a padded, zip-front leather jacket looks back over her shoulder in this November 1996 advert from American Vogue, one hand in a pocket and her long dark hair spilling past her shoulders, with ANDREW MARC set beneath her in serif capitals almost as wide as the page. Running up the left edge, in type you'd need to squint at, is "Photo: Chris Gbur." Gbur was on the company's payroll. By 2016 WWD was describing him as the brand's creative director, with more than three decades at Andrew Marc behind him, so this ad, at least, was made in-house. North Beach Leather cast its founder as the model, while this one had a member of staff behind the camera.

The name belongs to Andrew Marc Schwartz, who built the label with his wife, Suzanne, and according to WorthPoint she designed the womenswear. Encyclopedia.com dates the start to 1981 and a leather bomber trimmed with fur, while the company itself says 1982, and I can't tell which is right.

Nordstrom, Saks Fifth Avenue, Neiman Marcus and Bloomingdale's are the stores handwritten along the bottom of the ad, and all four still appear in The Sage Group's note on the 2004 deal in which the Schwartzes brought in GB Palladin Capital, part of Gordon Brothers, and stayed on to run the firm. G-III Apparel Group bought the brand in February 2008. The retailers on Andrew Marc's own site now are Nordstrom, Macy's, Dillard's and Wilsons Leather, which G-III also owns. Saks, Neiman Marcus and Bloomingdale's are gone from it, which I read as a quiet step away from the luxury department stores that carried the brand in 1996.

My best guess for the model is Mary Matthews, because collectors credit her in Andrew Marc ads from 1993 and 1994, at least one of them shot by Gbur, but nothing I've found names the woman in this one.

Sources:

This post is timestamped using Blockchain technology. Verify

Most Read

What readers opened most over the last 3 months.

  1. A Watermark and a Shrug
  2. The Quiet Authority of Exposure and ATC Together
  3. Four AI Heavyweights Shaping the Future
  4. Dawn Arrived
  5. Coins Left in Vinegar
  6. By 2028, Permission Is the Product
  7. Lavender and Leather at the Ralph Lauren Spring 1993 Show
  8. Nobody Knows What It Is Yet
  9. Thursday Was Ten Days Ago
  10. Sol, Terra, Luna, Astra